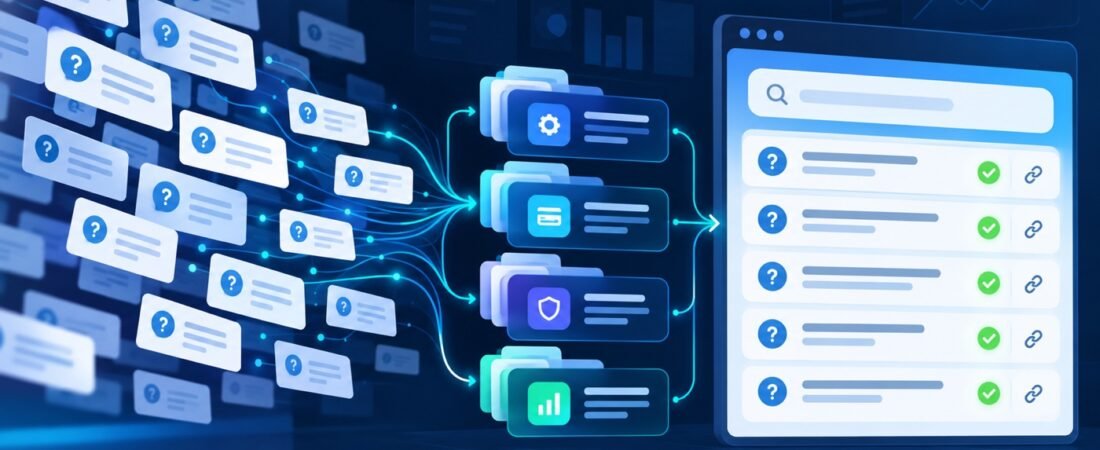
A support ticket FAQ can reduce repeated questions, but only if its answers match current policy and real product behavior. ChatGPT can help organize a large set of tickets into themes and draft plain-language questions. It should not decide what your company promises, guess why a problem occurred, or turn one unusual complaint into a universal answer.
OpenAI lists document synthesis, extraction, and sentiment analysis among supported file-upload tasks. Those capabilities can speed up the first pass. The dependable workflow is to preserve ticket references, separate observed questions from approved answers, and send every policy statement to the correct owner.
Set the scope before exporting tickets
Choose one product area, customer segment, and time window. “Build an FAQ from all support tickets” mixes unrelated issues and makes verification difficult. A better scope is “billing questions from self-service customers during the last 90 days.”
Define the finished output too. An internal agent guide can include diagnostic steps that should not appear on a public help page. A customer-facing FAQ needs approved wording, safe links, and a named content owner.
- Audience: customers, support agents, or both.
- Channel: public help center, chatbot source, or internal playbook.
- Time range: the period represented by the evidence.
- Included topics: the product or process boundary.
- Owners: roles that approve product, policy, legal, and support claims.
Remove customer data and label every source
Do not paste a raw inbox into ChatGPT. Follow your organization’s privacy, security, retention, and access rules. Remove names, email addresses, phone numbers, account identifiers, payment details, access tokens, free-form signatures, and any other data the analysis does not need. Replace them with neutral placeholders only when the relationship matters.
OpenAI documents data controls that vary by account and workspace. Those settings do not replace your organization’s policy. Confirm that you are using the approved workspace and that the material is permitted before uploading it.
Give each sanitized ticket a stable ID such as T-001. Keep the original-to-sanitized mapping in an approved system, not in the prompt. Include the date, product area, channel, and resolution status when those fields are allowed and useful.
You are preparing an evidence inventory for an FAQ. Do not draft answers yet.

Scope: [product area, audience, and time window]
Each ticket begins with a source ID such as T-001.

For every ticket, extract the customer's stated question, the product area, any documented error text, the resolution recorded by the support team, and unresolved details. Cite the source ID for every item. Do not infer a cause or resolution that is not recorded.
Cluster questions without hiding minority cases
Ask ChatGPT to group questions that express the same underlying need, even when customers use different words. Keep a count of source IDs in each cluster, but do not treat frequency as proof of business importance. A rare access or billing problem may deserve attention because of its impact.
Group the extracted questions by underlying customer intent.

For each cluster, provide:
- a neutral cluster name
- the source ticket IDs
- representative customer phrasings
- important differences between the tickets
- unresolved or minority cases that should remain separate

Do not merge tickets when the required answer, customer type, product version, or eligibility rule differs.
Review the clusters with a support lead. Split a group when one answer would be misleading for part of it. Preserve edge cases in a separate review list instead of discarding them as noise.
Separate customer evidence from approved answer sources
Tickets tell you what people asked and what an agent recorded. They do not automatically define the correct public answer. Build a second source set from current product documentation, approved policies, release notes, and owner decisions.
Label those sources D-001, D-002, and so on. Record an effective date or last-reviewed date when available. If an answer is not supported by an approved source, mark it as a gap. Do not turn the most common agent response into policy by repetition.
Draft FAQ entries with traceable support
Draft one entry at a time. The question should use language customers recognize. The answer should begin with the direct response, then add the smallest set of steps and exceptions needed.
Draft FAQ entries using the approved question clusters and documentation sources.

For each entry include:
1. customer-facing question
2. direct answer
3. numbered steps when action is required
4. confirmed exceptions or eligibility conditions
5. escalation path when the issue cannot be self-served
6. ticket IDs that support the question
7. documentation IDs that support every answer claim

If an answer lacks an approved source, write [OWNER INPUT NEEDED]. Do not invent product behavior, policy, time estimates, fees, eligibility, or escalation owners.
Remove internal source IDs from the published copy only after review. Keep them in the working version so future editors can trace why an entry exists and which documents support it.
Audit contradictions and risky wording
Run a focused audit before owner review. Look for absolute promises, unsupported timelines, vague escalation language, stale interface labels, and answers that conflict with another entry.
Audit the FAQ draft against the ticket inventory and approved documentation.

Flag:
- answer claims without a documentation ID
- contradictions between entries
- unapproved promises or deadlines
- words such as always, never, guaranteed, instant, or free
- interface labels that need current-product verification
- instructions that differ by plan, region, role, or product version
- questions whose source tickets were merged despite different answers

List the FAQ entry, the issue, the supporting source IDs, and the owner who needs to resolve it. Do not rewrite unresolved policy.
Test the FAQ against real questions
Hold back a small set of sanitized tickets that were not used during drafting. Ask a support reviewer to find the best FAQ entry for each question. Record whether the entry answers the question, partly answers it, sends the reader to the correct next step, or does not fit.
Do not optimize only for coverage. Check correctness, clarity, and safe escalation. If one broad entry appears to cover many tickets but requires several exceptions, split it into narrower entries.
Evaluate each held-out ticket against the reviewed FAQ.

Classify the result as answered, partly answered, correctly escalated, or not covered. Cite the ticket ID and FAQ entry. Explain the mismatch using only the ticket and approved answer sources. Propose a new entry or a narrow revision, but mark any new policy claim [OWNER INPUT NEEDED].
Publish with ownership and a review date
Before publication, confirm links, interface labels, product names, plan restrictions, and escalation paths. Assign an owner role and a practical review trigger, such as a product release, policy change, or recurring ticket pattern. A calendar review can help, but event-based updates are often more useful.
- The scope and audience are explicit.
- Customer data was removed under the approved process.
- Every question traces to ticket evidence.
- Every answer claim traces to approved documentation.
- Minority and high-impact cases remain visible.
- Held-out tickets were tested against the FAQ.
- Owners resolved gaps before publication.
ChatGPT is most useful here as an organizer and drafting assistant. Your support and product owners remain responsible for what the FAQ promises and whether the answer still matches reality.
Want more practical AI workflows with built-in checks? Join ZippByte Weekly for concise prompts and verification habits you can adapt to your own work.