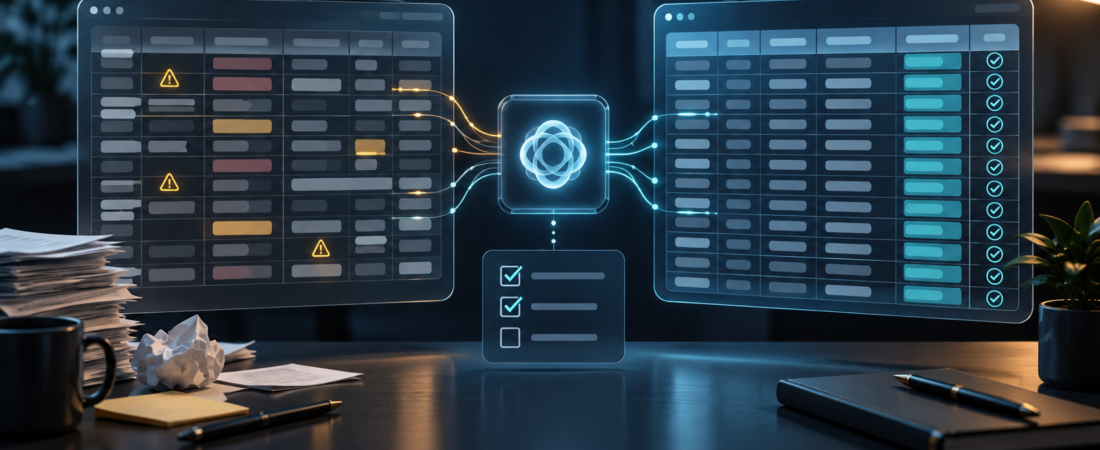
A CSV export can look simple until you try to use it. Dates arrive in two formats. One category has three spellings. A total row sits inside the records. A blank amount might mean zero, missing, or not applicable. Cleaning those problems by hand is tedious, but asking AI to “fix the file” can silently change its meaning.
The safer approach is to keep the original untouched, define the rules, ask ChatGPT to produce a separate cleaned copy, and reconcile every important change. OpenAI’s messy-data use case recommends that copy-first pattern and a data-quality note. The steps below turn it into a repeatable review process for a small CSV export.
This is a workflow recommendation, not a promise that ChatGPT will detect every error. File features can vary by plan and workspace. If your account cannot accept an upload, the same checklist works with a permitted sample pasted into a chat or with another tool that can read a CSV.
Start with a clear definition of a row
Before uploading anything, decide what one row represents. Is it one order, one customer, one invoice line, or one daily total? That answer determines whether a repeated value is a duplicate. Two orders from the same customer are not duplicate orders. Two rows with the same order ID may still be legitimate if each is a different line item.
For example, imagine a fictional sales export with order_id, order_date, region, amount, and status. The first cleaning decision is: one row represents one order, and order_id should be unique. If the real export contains line items instead, use a compound key such as order_id plus line_id. Do not let ChatGPT choose the key without telling you.
Check your data-sharing rules before upload. Remove or mask personal information that is not needed for the task, and use only files your organization permits in that workspace. Keep the original file in its source location. Make a working copy with a date or version in its filename. Record the original row count and the total of any numeric field you will later reconcile.
Ask for a diagnosis before a cleaned file
The first prompt should inspect, not edit. Give ChatGPT the row definition and ask it to list problems with examples and counts. A useful opening prompt is:
Inspect the attached CSV. One row should represent one order, and order_id should be unique.

Do not clean or rewrite the file yet. Report the column names and row count. Identify mixed date formats, blank required fields, invalid amounts, category aliases, possible duplicates, and any summary rows inside the data. Give the affected row IDs or row numbers and a count for each issue. If you cannot inspect the entire file, say so.
Compare that report with the original. If it says there are no duplicates, check the identifier column yourself. If it treats a blank amount as zero, challenge that assumption before moving on. The UK Government Data Quality Framework distinguishes completeness, uniqueness, consistency, validity, timeliness, and accuracy. Those are useful lenses, but they do not supply the business rules for your file.
Write the cleaning rules explicitly
Turn the diagnosis into a small rule sheet. In the fictional order example, the rules might be:
- Preserve every source row ID in an
original_row_idcolumn. - Convert unambiguous dates to
YYYY-MM-DD. Flag ambiguous dates such as03/04/2026instead of guessing the day and month. - Map only approved region aliases, such as
North EastandN.E.toNortheast. - Remove a row only when it is clearly a pasted summary, and log its source row ID.
- Keep blank amounts blank. Do not replace them with zero.
- Flag repeated
order_idvalues for review. Do not delete either row automatically.
Notice what the rules do not say. They do not tell the model to infer a missing price, decide which duplicate is “correct,” or merge two people with similar names. Those require external evidence or a person who owns the data.
Give ChatGPT the approved rules and ask for a plan before it writes an output:
Use only the cleaning rules below. Show a proposed change log with original_row_id, column, old value, new value, rule applied, and reason. Put uncertain cases in an exceptions list and leave their values unchanged. Do not create the cleaned CSV until I approve the proposed transformations.

Rules: [paste approved rules]
Review the plan for overreach. A model may group similar text values that should remain distinct. For example, “West” could mean a sales region or a person’s surname. A change log makes that mistake easier to catch than a polished output file alone.
Produce a copy and an exception report
After reviewing the plan, ask for a new file rather than an in-place edit. Request three outputs: the cleaned CSV, a change log, and an exceptions list. The last two are part of the deliverable, not optional commentary.
Create a new cleaned CSV from the original. Do not overwrite the source. Apply only the approved rules. Preserve original_row_id and original column names unless a rule explicitly changes them.

Also provide: (1) a machine-readable change log for every changed or removed source row, (2) an exceptions list for ambiguous dates, disputed duplicates, and missing required values, and (3) before-and-after row counts and numeric totals. Do not silently resolve exceptions.
Open each output. A summary in the chat is not enough. Check that the CSV has the expected columns, can be opened by your spreadsheet application, and retains its row IDs. Keep the exception report beside the cleaned file so the next person does not mistake unresolved records for clean ones.
Reconcile before using the cleaned data
Reconciliation answers a simple question: can you explain the difference between the input and output? If you started with 120 rows and intentionally removed two pasted totals, the cleaned file should contain 118 data rows. If it contains 117, investigate the extra missing row. This is an illustrative calculation, not a statistic about ChatGPT.
For amounts, compare the sum of valid source data rows with the sum in the cleaned file. If you only standardized dates and region names, the amount total should not change. If a currency string was converted to a number, spot-check the parsed amount and currency. Never add values in different currencies without an explicit conversion rule.
Use this verification prompt to generate a review report, then confirm the numbers independently in your spreadsheet tool:
Compare the original CSV with the cleaned CSV by original_row_id. Report source rows, output rows, removed summary rows, unresolved duplicate IDs, blank amounts, and amount totals. List every ID that appears in only one file. For each numeric field, show whether its total changed and explain why. Do not call the file ready if a difference is unexplained.Also sample a few records from each change type. Inspect a converted date, a mapped alias, an untouched blank, a flagged duplicate, and the first and last data rows. Sampling cannot prove the entire file is correct, but it often reveals a bad rule quickly. For higher-stakes data, validate all changed records or use deterministic checks written for the file’s schema.
Know when to stop and ask for evidence
Some defects are not cleaning tasks. An amount of -50 may be a refund, a correction, or an error. A missing region could be filled from a trusted customer master, but only if you have permission and a reliable join key. A date like 04/05/2026 cannot be resolved from format alone. Put these in the exceptions list with a proposed owner or source of truth, not an AI guess.
The government framework also separates validity from accuracy: a value can have the expected format and still be wrong. A neatly formatted order date does not prove the order happened that day. If the clean file will drive billing, compliance, or a consequential decision, get the responsible expert to review the rules and the exceptions before use.
A short checklist for the next export
Keep the original, the rule sheet, the cleaned copy, the change log, and the exceptions together. On the next export, compare its columns and date conventions with the previous one before reusing the rules. A changed source system can turn yesterday’s safe mapping into today’s mistake.
The goal is a file whose changes you can explain. ChatGPT can help identify patterns and prepare a copy. The decision about what a row means, what may be changed, and whether the result is fit for use stays with you.
Want more practical AI workflows with built-in checks? Join ZippByte Weekly for concise prompts and review habits you can adapt to your own work.