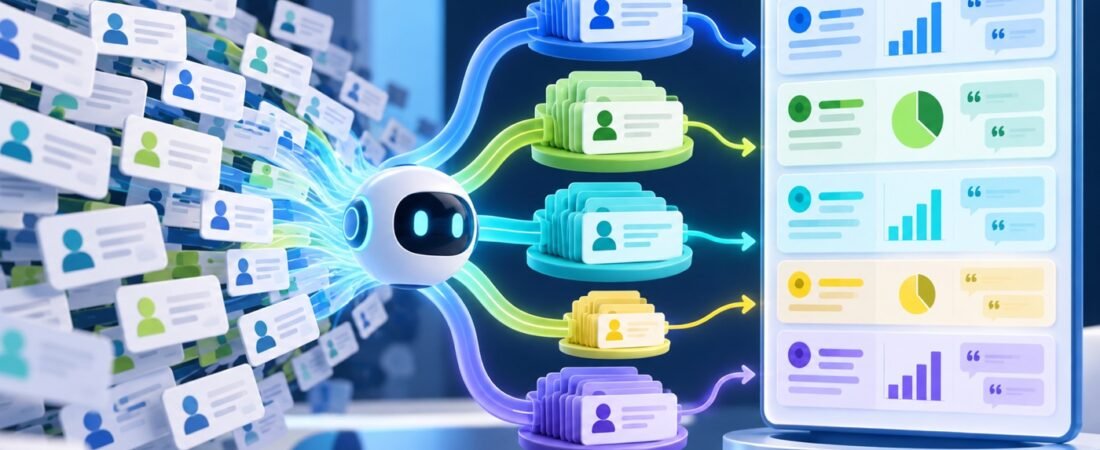
Survey comments can suggest explanations for a score, reveal language customers use, and surface problems that a multiple-choice question missed. ChatGPT can help organize responses, but a quick summary can flatten disagreement and hide a small group with an important experience.
A stronger workflow keeps every insight tied to response IDs, compares segments separately, and gives minority views a deliberate review path. The goal is not to make qualitative feedback look mathematically precise. It is to create a transparent map that a human analyst can challenge and verify.
Define the question before uploading comments
Start with the decision the analysis will inform. “Summarize all feedback” encourages broad themes with little practical value. A focused question might ask what blocked first-time users during onboarding, why some subscribers considered canceling, or which parts of a workshop participants wanted expanded.
Record the survey question, field dates, population, response channel, and any known sampling limits. Decide which segments matter before viewing the results. Creating segments after seeing a dramatic comment can turn an anecdote into a misleading story.
- Decision: what someone will do with the result.
- Unit: one respondent, one comment, or one answer to a specific question.
- Scope: the date range, product, audience, and survey question.
- Segments: groups that can be compared safely and meaningfully.
- Exclusions: blank, test, duplicate, or out-of-scope responses.
Remove identifiers and preserve row-level evidence
Follow your organization’s privacy, consent, retention, and access rules before using any AI tool. Remove names, email addresses, account numbers, phone numbers, precise locations, and free-text details that could identify a person unless the approved task genuinely requires them.
OpenAI documents data controls that differ by account and workspace. Those controls do not replace local policy. Confirm the approved workspace and permitted data before uploading a file.
Assign each sanitized response a stable ID such as R-001. Keep allowed segment fields in separate columns. Preserve the original wording in a controlled working copy so reviewers can trace every theme back to evidence.
Inspect this sanitized survey dataset before analysis.

Report:
- available columns and likely meanings
- blank, duplicate, or malformed rows
- segment fields present
- response IDs that are missing or duplicated
- comments that appear out of scope for the stated survey question
- any remaining text that may contain identifying information

Do not summarize themes yet. Do not infer missing values.
Create a codebook from a sample
Review a varied sample before coding the full dataset. Include short and long comments, positive and negative responses, different segments, and comments that appear unusual. Ask ChatGPT to propose descriptive codes, then have a human revise the definitions.
A useful codebook defines what belongs, what does not, and how to handle overlap. “Usability” is too broad if it mixes navigation, speed, instructions, and accessibility. The codebook can allow more than one code per response when the comment truly covers multiple issues.
Propose a draft codebook from this sample of survey comments.

For each code include:
1. short neutral label
2. definition
3. inclusion rule
4. exclusion rule
5. one supporting response ID
6. codes it may overlap with

Keep positive, negative, and mixed experiences distinct. Preserve unusual comments in an "other or review" bucket rather than forcing a fit.
Code every response and retain ambiguity
Apply the revised codebook to the full set. Require response IDs for every assigned code and allow an uncertain label when evidence is weak. Do not force sentiment onto a factual request, and do not infer a respondent’s motive, demographic identity, or emotional state.
Apply the approved codebook to each response.

Return one row per response ID with:
- assigned code or codes
- sentiment only when explicitly supported by the wording
- a short evidence excerpt
- confidence: clear, mixed, or uncertain
- review note for ambiguous or out-of-codebook comments

Do not infer demographics, intent, severity, or cause. Preserve the original response ID.
Human-review a sample from every code, plus all mixed, uncertain, and out-of-codebook responses. If reviewers repeatedly disagree, clarify the definition and recode the affected rows.
- R-001 reports a quick first-time setup. Code: setup speed, positive.
- R-002 also reports a quick setup. Code: setup speed, positive.
- R-003 reports waiting at the final setup step. Code: setup delay, negative.
- R-004 reports being unable to reach the final button using a keyboard. Code: keyboard access, negative, review required.
Count each response once within each code. This sample has two positive setup-speed responses, one delay response, and one keyboard-access response. A summary saying only that setup was usually quick would omit two different problems. Keep R-004 visible for accessibility review even though only one record raises it. The comment does not establish the technical cause.
These are constructed examples, not customer quotations or findings. If one real comment receives two codes, the sum of code counts can exceed the number of responses. Show the counting rule and denominator rather than treating code totals as unique people.
Keep minority and high-impact views visible
Frequency is useful, but it is not the same as importance. A small cluster may expose an accessibility barrier, a safety issue, a broken payment path, or an experience limited to one plan or region. Treat those as review candidates rather than statistical conclusions.
Set a rule before summarizing: report common themes, segment-specific themes, contradictory views, and low-frequency items with potentially high consequences. Avoid calling a pattern “rare” unless the denominator and counting method are clear.
Create a minority-view review list from the coded responses.

Include:
- low-frequency codes
- comments that contradict a common theme
- issues limited to one segment, plan, region, or product version
- possible accessibility, safety, payment, privacy, or account-access concerns
- uncertain comments that could change the interpretation

Cite every response ID. Do not rank severity without an approved rule.
Compare segments without overclaiming
Analyze relevant segments separately before combining them. A theme that appears across all respondents may mean something different for new customers than for experienced users. Use counts as a navigation aid, not as proof of causation or population prevalence.
Check whether segment sizes differ, whether the survey question was shown consistently, and whether respondents could submit multiple comments. If the data cannot support a comparison, say so directly.
Compare coded themes across the approved segments.

For each segment provide:
- number of included response IDs
- prominent themes with supporting IDs
- themes found only in that segment
- contradictory or mixed evidence
- limitations that prevent a fair comparison

Use descriptive language. Do not claim statistical significance, causation, or population prevalence.
Write findings with an evidence trail
Structure the report around the decision, not around every possible theme. For each finding, state what appeared in the responses, identify relevant segments, include representative excerpts that are safe to share, and link back to response IDs. Separate observations from recommended actions.
Ask a reviewer to inspect the original sanitized comments for each major finding and every consequential minority item. Look for excerpts taken out of context, duplicate respondents, code drift, and conclusions that ignore conflicting evidence.
Draft an evidence-linked findings report.

For each finding include:
1. neutral finding statement
2. relevant segment and response count
3. supporting response IDs
4. contradictory or minority evidence
5. limitations
6. recommended follow-up, clearly labeled as a recommendation

Do not create percentages unless the denominator and counting rule are provided. Do not invent quotations, causes, or customer characteristics.
Complete a final quality check
- The analysis question and decision are explicit.
- Identifiers were removed under an approved process.
- Every response has a stable ID.
- The codebook has inclusion and exclusion rules.
- Ambiguous responses and reviewer disagreement remain visible.
- Minority and high-impact views have a separate review path.
- Segment comparisons state their limits.
- Every finding traces to specific response IDs.
- Recommendations are separate from observed evidence.
ChatGPT can accelerate coding and organization, but the defensible result comes from traceability. When a reader can move from a finding to the relevant comments and understand what the analysis cannot prove, the summary becomes more useful and less likely to erase the people it describes.
Want more practical AI workflows with built-in checks? Join ZippByte Weekly for concise prompts and verification habits you can adapt to your own work.
Sources
The coding and review steps above are ZippByte’s recommended workflow. The following sources support file handling, data controls, and broader generative-AI risk management; they do not validate these prompts as a statistical method.